Publications

Yiran Ling*, Qing Lian*, Jinghang Li, Qing Jiang, Tianming Zhang, Xiaoke Jiang, Chuanxiu Liu, Jie Liu, and Lei Zhang

* Equal contribution

European Conference on Computer Vision (ECCV), 2026

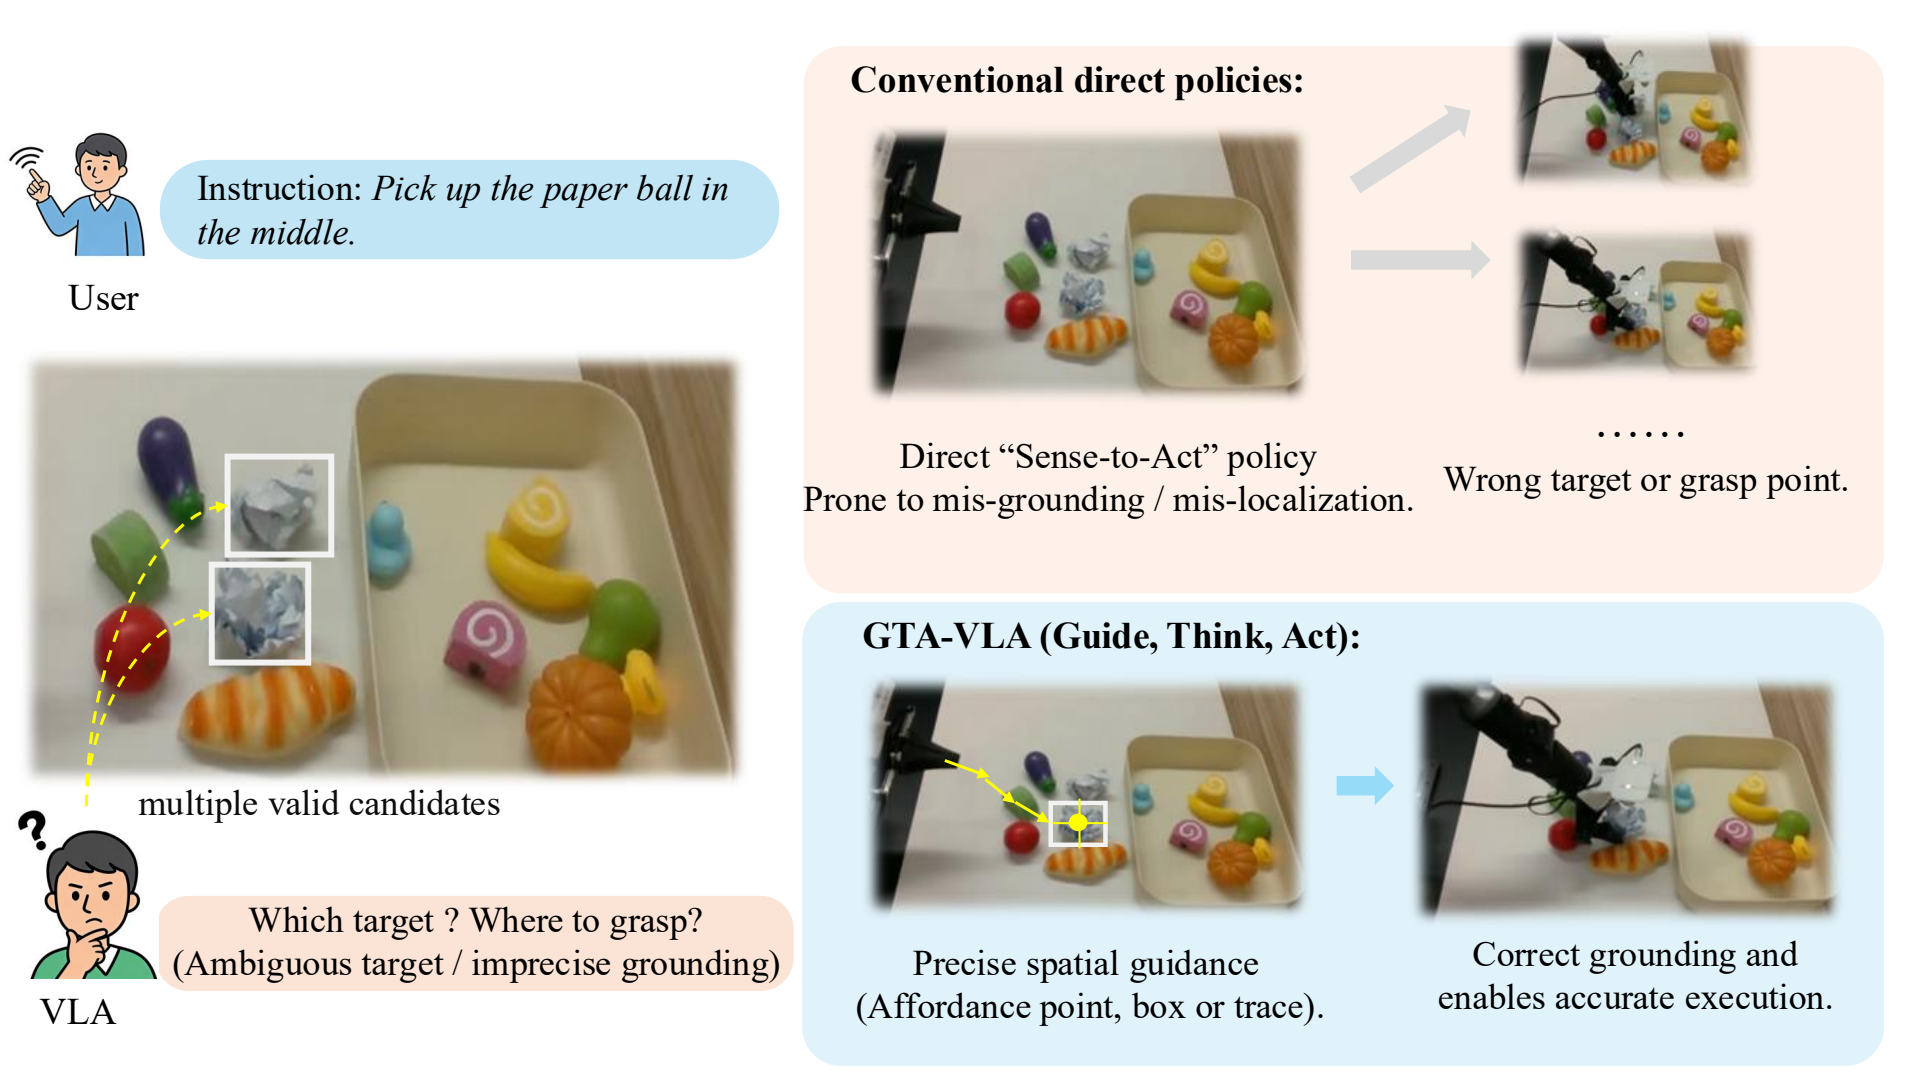
GTA-VLA introduces spatially steerable embodied reasoning: a user can provide an affordance point, box, or trace to resolve ambiguity and guide a robot policy toward accurate execution. The method reaches an 81.2% success rate on the SimplerEnv WidowX benchmark and improves robustness under out-of-domain visual shifts.
Jing Jiang*, Yiran Ling*, Ruonan Li, Dimitrios Stamoulis†, and Jie Liu†

* Equal contribution · † Corresponding authors

Conference on Empirical Methods in Natural Language Processing (EMNLP), 2026

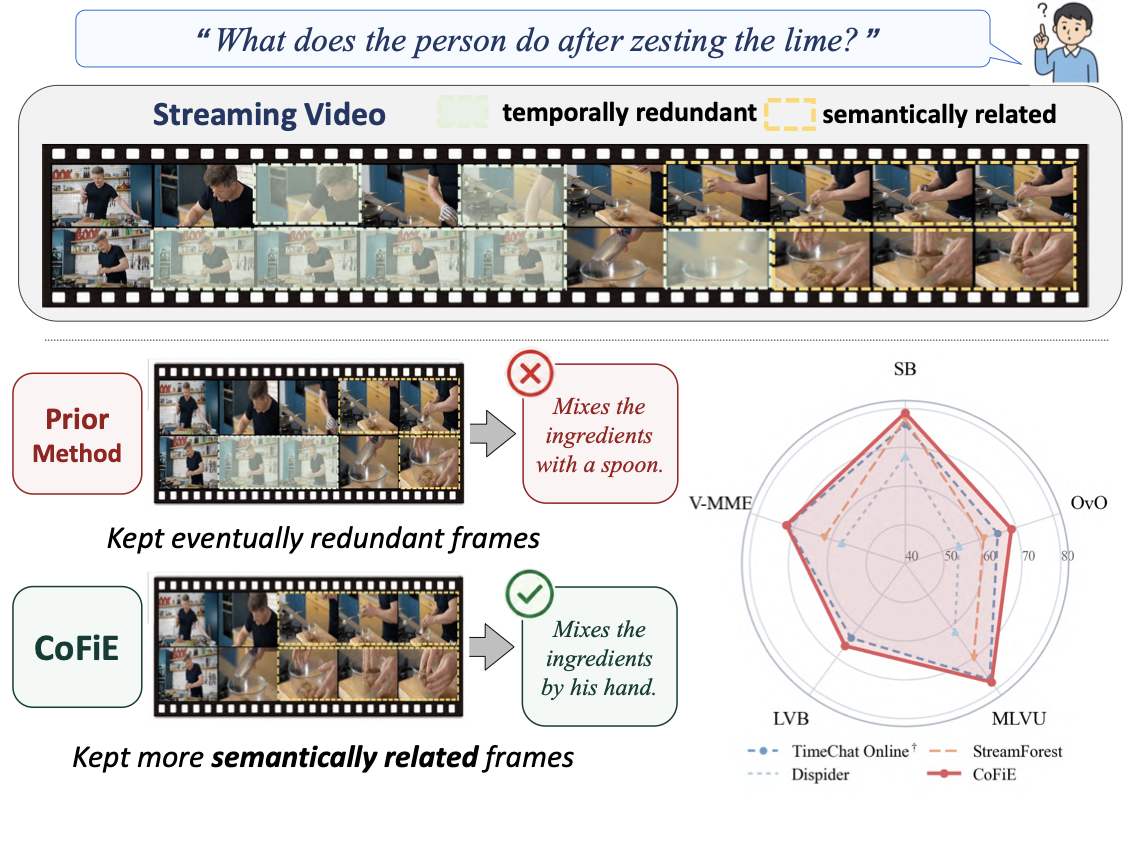
CoFiE accelerates streaming video understanding through coarse-to-fine evidence selection. It removes redundant frames before visual encoding, then refines query-relevant evidence during multimodal prefill, reaching state-of-the-art accuracy-efficiency trade-offs with up to 2.54× lower end-to-end inference latency.