Guide, Think, Act: Interactive Embodied Reasoning in Vision-Language-Action Models
Published in European Conference on Computer Vision (ECCV), 2026
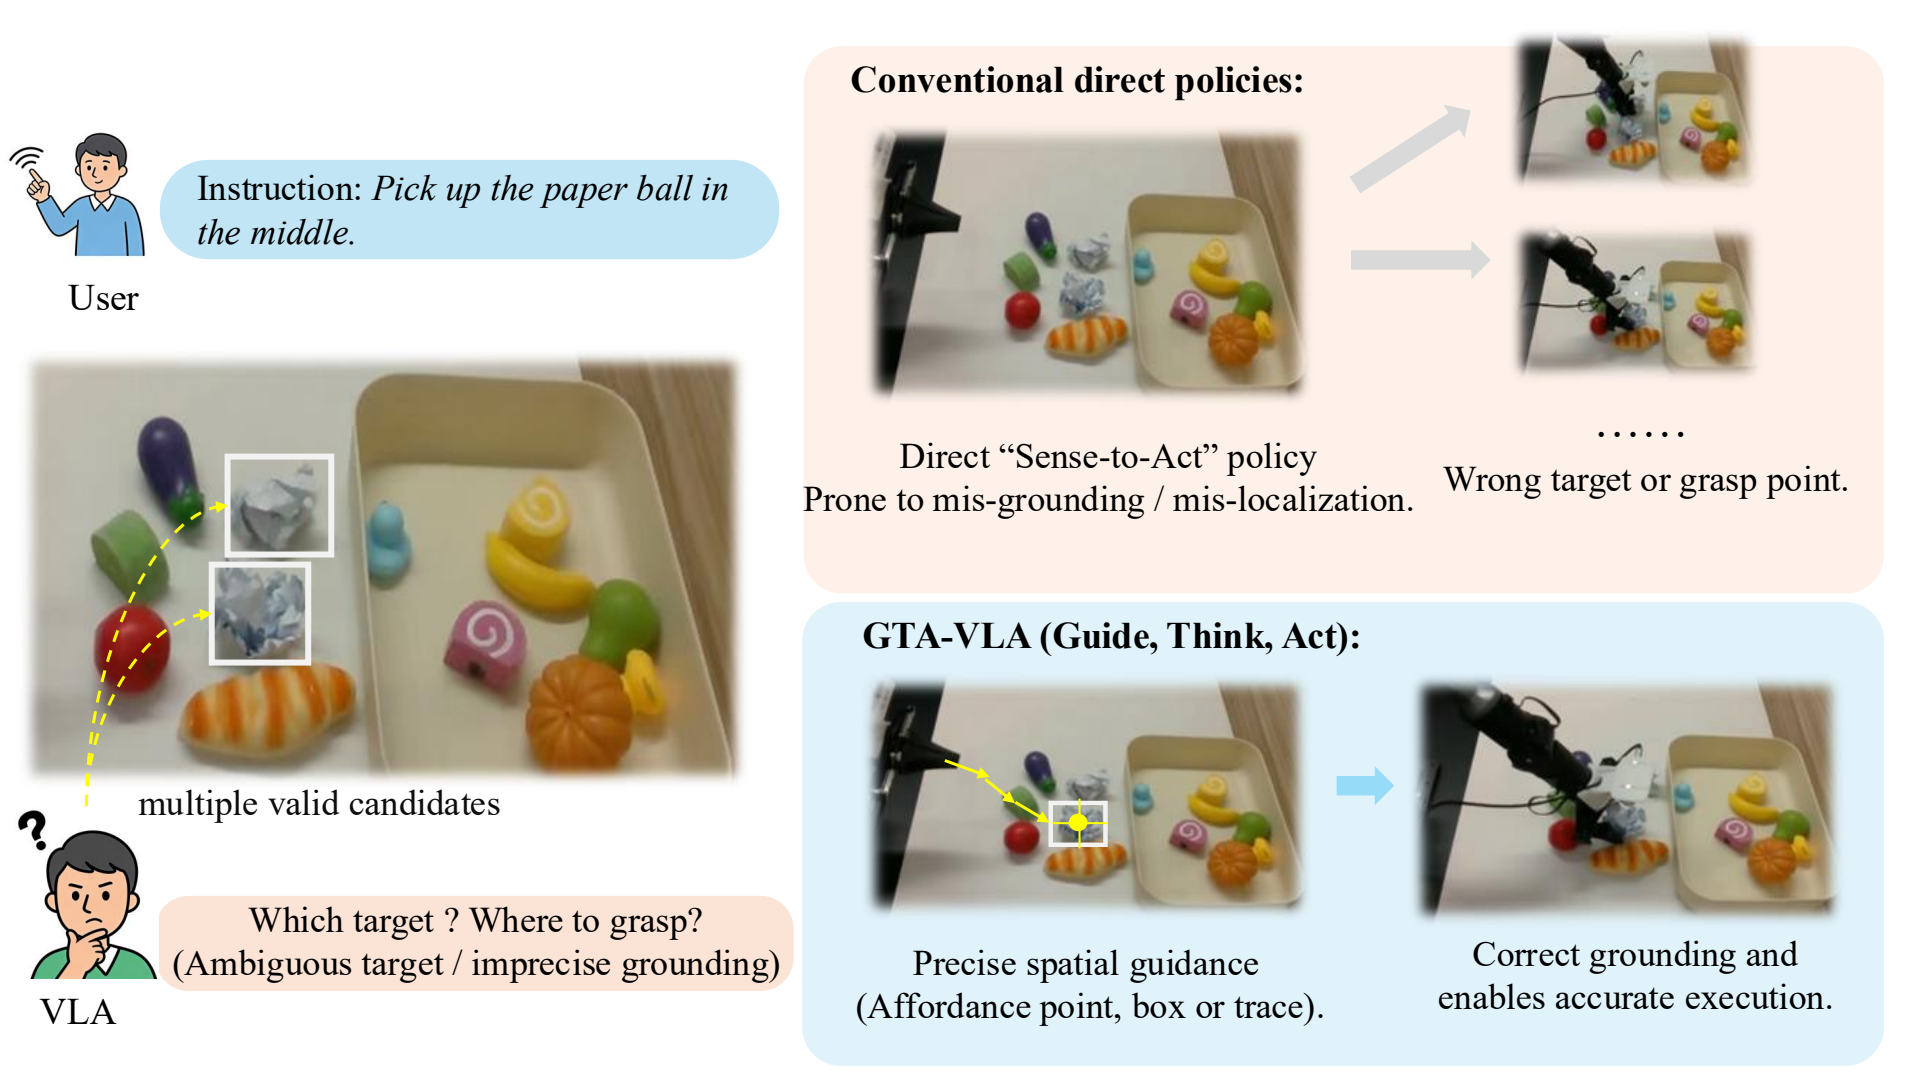
GTA-VLA is an interactive vision-language-action framework for spatially steerable embodied reasoning. Users can provide an affordance point, box, or trace to resolve spatial ambiguity and guide the policy toward accurate execution.
The framework integrates external guidance with a spatial-visual chain of thought and couples the reasoning module with a lightweight reactive action head. GTA-VLA achieves an 81.2% success rate on the SimplerEnv WidowX benchmark and improves robustness under out-of-domain visual shifts and ambiguous scenes.
Recommended citation: Yiran Ling*, Qing Lian*, Jinghang Li, Qing Jiang, Tianming Zhang, Xiaoke Jiang, Chuanxiu Liu, Jie Liu, and Lei Zhang. Guide, Think, Act: Interactive Embodied Reasoning in Vision-Language-Action Models. European Conference on Computer Vision (ECCV), 2026. (* Equal contribution.)
Download Paper